About
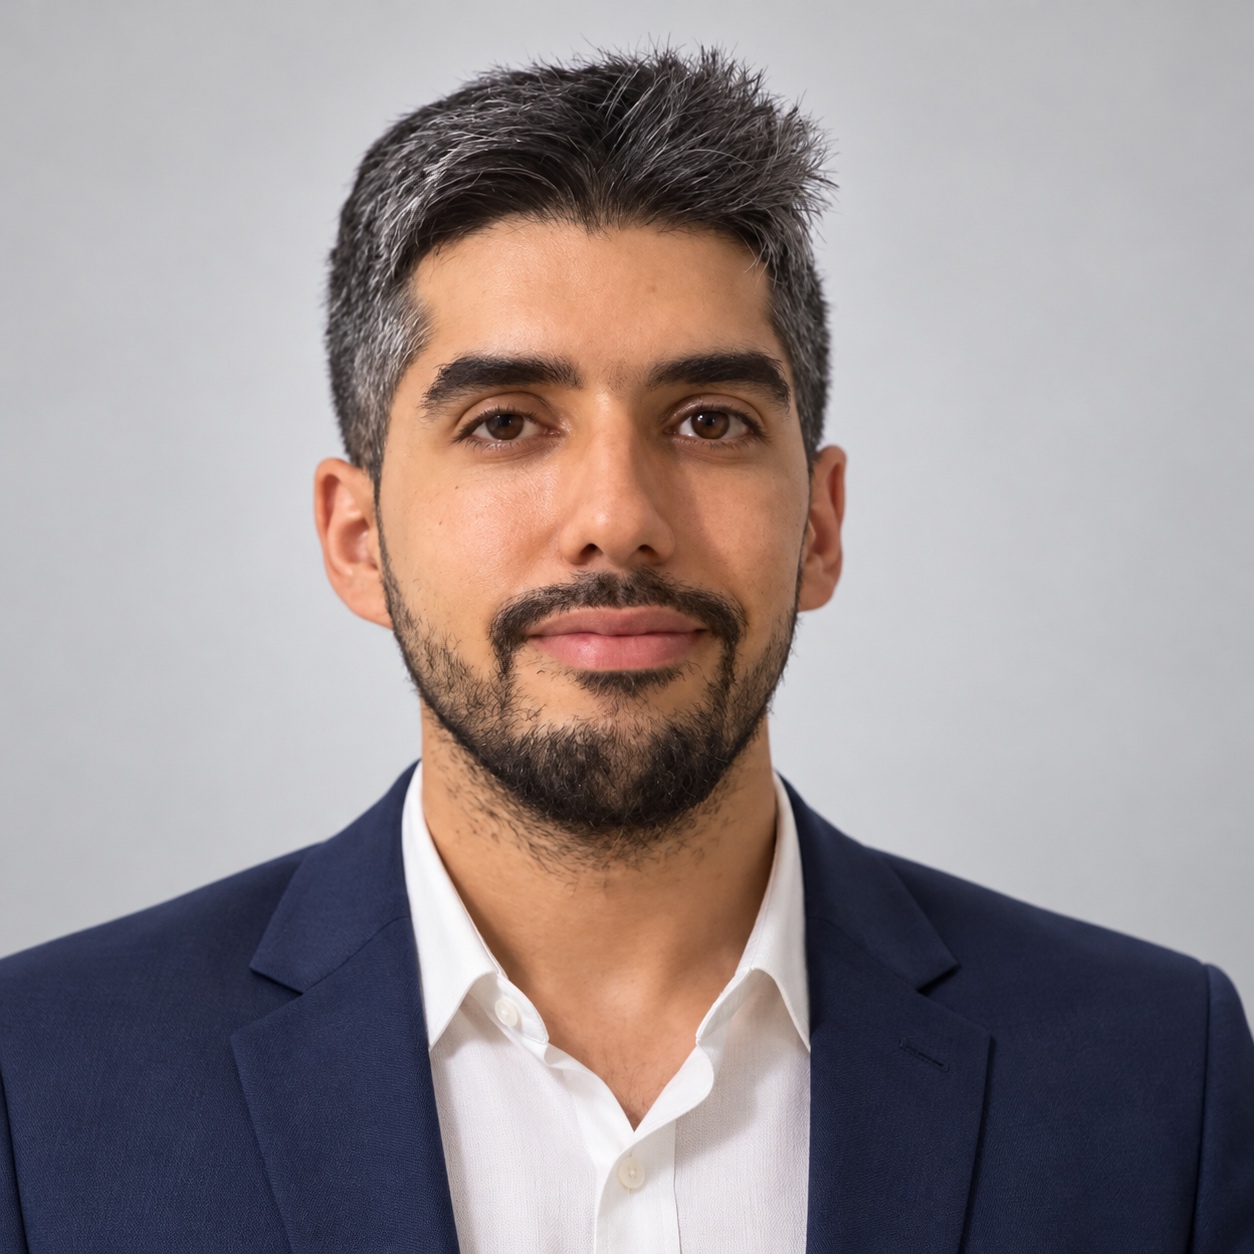
I build backend systems where being wrong is expensive. For five years that has meant production work in fintech and insurance: payments, banking pipelines, risk calculation — systems moving millions of transactions, where every number has to be explainable after the fact.
Most of what I know came from those systems under real load, not from slides. I've watched batch jobs miss their window, chased numbers that were off by a cent across millions of rows, and sat through enough production incidents to stop trusting anything I haven't measured. The lesson every time: correctness and performance aren't a trade-off. They're the same discipline, applied at different scales.
Experience
Where I've done it
- Years in production
- 5+
- Regulated industries
- 2
- Transactions processed
- 1M+
Payments
Led feature and architecture work
On a regulated payments platform, where a design decision has to survive compliance review as well as code review.
Banking
Calculation and reconciliation pipelines
IFRS9 and reconciliation pipelines where every output number needs an audit trail back to the regulation that produced it.
Insurance
Risk-calculation and rating engines
Pricing and risk logic that has to be explainable to actuaries and auditors, not just correct on a test suite.
Scale
Millions of transactions, every one explainable
Batch systems that have to finish overnight and still be right. Enough production incidents to have strong opinions about both.
How I work
What I hold myself to
- 01
Correctness and performance are one discipline
Fast but wrong is worthless; correct but too slow to run is worthless too. I refuse to pick one.
- 02
Know what the cost is before cutting it
My last columnar rewrite looked like a distributed-systems problem and turned out to be cache locality. Measure first.
- 03
Every number has an audit trail
If an output can't be traced back to the input and the rule that produced it, it isn't done.
- 04
Regressions get caught in CI, not production
Performance is tested like behaviour: benchmarks with budgets that fail the build.
Currently building
Most of my current work is open source: CedarRecon, a financial reconciliation engine, and CedarRisk, an insurance rating engine — plus BenchmarkGate, the performance regression tool I built once "eyeball the CI log and hope someone notices" stopped being good enough.
See the projects page →Expertise
What I work with
- C#
- .NET
- SQL Server
- DDD
- CQRS
- Linux
- Distributed Systems
- Docker
- Cloud Infrastructure
- Redis
- Clean Architecture
- Kubernetes
- BenchmarkDotNet
- Agentic AI
- C#
- .NET
- SQL Server
- DDD
- CQRS
- Linux
- Distributed Systems
- Docker
- Cloud Infrastructure
- Redis
- Clean Architecture
- Kubernetes
- BenchmarkDotNet
- Agentic AI